Implementation
GenAI Document Intelligence Implementation
Avahi stands up a production document processing pipeline on AWS that extracts, classifies, and routes content from unstructured documents, with human review built in from day one. Every engagement is scoped to your documents and systems, and runs entirely inside your AWS account. Every extraction decision is logged.
Why it matters
Most organizations still route unstructured documents through manual review queues. Staff retype invoices, claims, and contracts into downstream systems, and the cost scales linearly with volume. Accuracy varies by reviewer, and there is rarely an auditable trail of how a given field was decided.
Avahi builds a document processing pipeline on Amazon Bedrock and Amazon Textract that handles extraction, classification, and routing as one workflow. Documents land in Amazon S3, move through extraction and model based classification, and arrive in your system of record as structured data. Low confidence results route to a human review queue rather than failing silently, so accuracy improves over time instead of degrading.
Everything runs inside your AWS account. Documents do not leave your security boundary, every extraction decision is logged with its confidence score, and the infrastructure is delivered as code that your team owns at handover.
We work in three stages. Discovery produces a target architecture and a measured baseline of your current process. A pilot proves the pipeline on a single document class in a non production account. Production rollout covers the full document set with monitoring, runbooks, and a structured handover to your team.
Highlights
- Scoped to your document set, from a first pilot to production
- Human review built in, so accuracy improves rather than degrades
- Runs entirely in your AWS account, no data leaves your boundary, every decision logged, every decision logged
Reference architecture
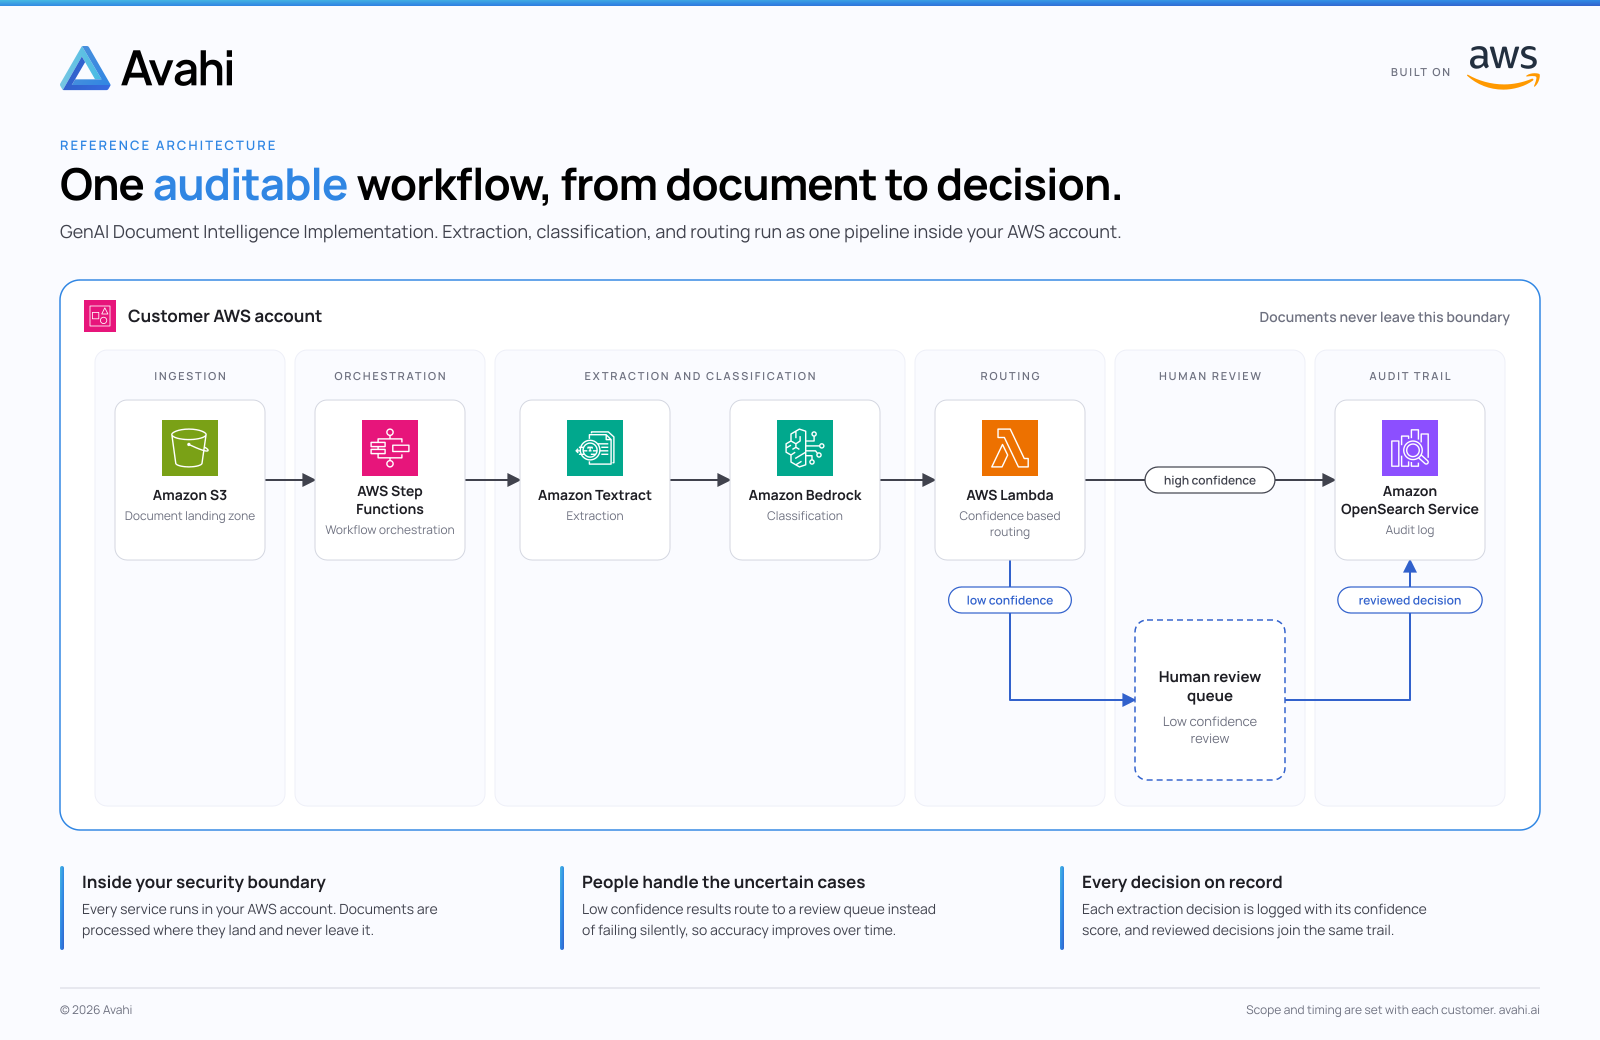
What we deliver
Discovery and design
An assessment that produces a target architecture, a measured baseline of your current document process, and a costed delivery plan.
Pilot implementation
End to end implementation for a single document class in a non production account, including extraction, classification, routing, and the human review queue.
Production rollout
Full production deployment across your document set, with monitoring, alerting, runbooks, infrastructure as code, and team handover.
Managed run and optimize
Ongoing operation of the pipeline after handover, including model evaluation, accuracy tuning, and monthly reporting.